Summarize This Article With AI
Chunking in retrieval-augmented generation (RAG) means dividing source material into retrievable units before embedding and indexing it. The best RAG chunking strategy is not one fixed token count. It is the method that preserves the evidence needed to answer your users’ questions while keeping each retrieved unit focused enough to rank well. Choose it from document structure, query type, embedding behavior, retrieval method, and measured results—not from a default copied from a tutorial.
Key Takeaways
- Start with the natural structure of the source—headings, paragraphs, clauses, functions, rows, or records—before applying an arbitrary size limit.
- Smaller chunks can improve retrieval precision but may separate a claim from its explanation, qualifier, table heading, or source context.
- Larger chunks preserve context but may contain several topics, weaken ranking, consume more prompt space, and repeat irrelevant text.
- Overlap is a boundary-repair mechanism, not a quality setting that should automatically be increased.
- Metadata should identify where a chunk came from, what it represents, which version is current, and who is allowed to retrieve it.
- Evaluate chunking with representative questions and retrieval evidence before changing the language model or prompt.
What Is Chunking in RAG?
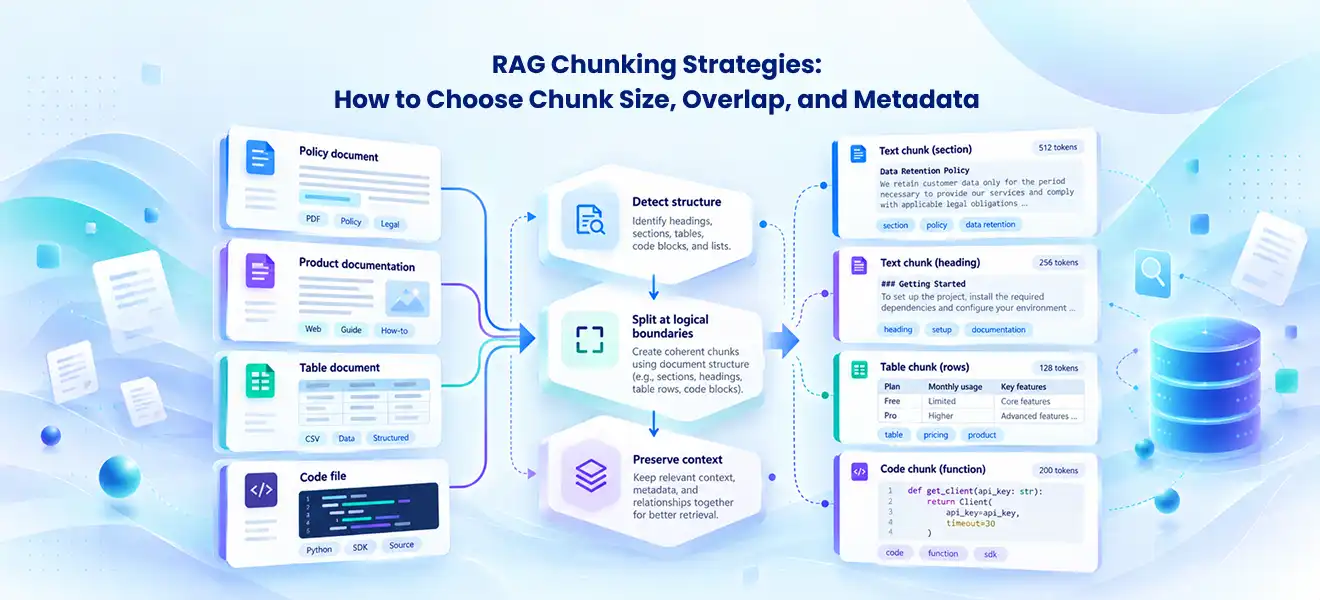
Chunking is the ingestion step that turns a document, page, record, or codebase into smaller retrieval units. Each unit may be embedded, indexed, filtered, ranked, and eventually supplied to a language model as evidence. Microsoft’s RAG chunking-phase guidance likewise treats chunking as a preparation and indexing decision rather than a universal token setting.
A source document and a retrieval chunk serve different purposes. A document is written for people to read in sequence. A chunk is designed to be found independently when a user asks a question. Effective chunking therefore preserves enough local meaning for retrieval without pretending that every source has the same structure.
Consider a return policy. The heading may name the policy, one paragraph may define the standard window, and the next may list exceptions. Splitting those elements into unrelated chunks can retrieve the rule without the exception. Combining the entire policy manual into one unit can bury the answer among unrelated topics. The practical objective is to create a retrievable evidence unit whose boundaries match the questions users ask.
Chunking sits between document preparation and indexing. A broader production design also needs source permissions, freshness, retrieval, ranking, generation, citations, and monitoring. Those responsibilities are covered in WebbyCrown’s guide to a secure, permission-aware RAG architecture. This article stays focused on segmentation and its direct effect on retrieval evidence.
Why Chunking Changes Retrieval Quality
Retrieval systems do not simply “understand the whole document.” They compare a query with indexed units and return a limited set. The boundaries of those units influence what can be found and what context arrives with it.
Precision and context pull in different directions
A focused chunk is easier to match to a narrow question. Yet a chunk that is too small may omit a definition, subject, date, condition, or preceding heading. A large chunk carries more context, but its embedding may represent several competing ideas. Retrieval can then match the general topic while missing the exact answer.
This is why “smaller is better” and “larger is better” are both incomplete rules. The right granularity depends on the evidence unit. A glossary definition, contract clause, troubleshooting procedure, API endpoint, and financial table should not automatically share one splitter.
Boundary errors become answer errors
Poor boundaries commonly create four problems:
- Orphaned statements: a sentence loses the heading or entity that gives it meaning.
- Separated conditions: a rule is retrieved without its exception or eligibility condition.
- Broken structures: a table row loses its headers, or a numbered step loses the preceding step.
- Mixed topics: one chunk contains several unrelated concepts, making ranking and citation less precise.
These failures can look like a model problem even when the model is faithfully using incomplete evidence. Before changing the prompt or model, inspect the retrieved chunks.
Chunking interacts with retrieval
Chunking cannot be optimized in isolation. Dense retrieval may favor semantically coherent passages. Keyword retrieval may need exact identifiers, error codes, names, or phrases. Metadata filters may eliminate irrelevant versions or departments before ranking. Reranking may select a better passage from a larger candidate set.
If your corpus contains both conceptual language and exact technical strings, read WebbyCrown’s comparison of hybrid, semantic, and keyword search for RAG. Keep the responsibilities separate: this page determines what the retrieval units should be; that page determines how those units should be found.
Seven Practical RAG Chunking Strategies
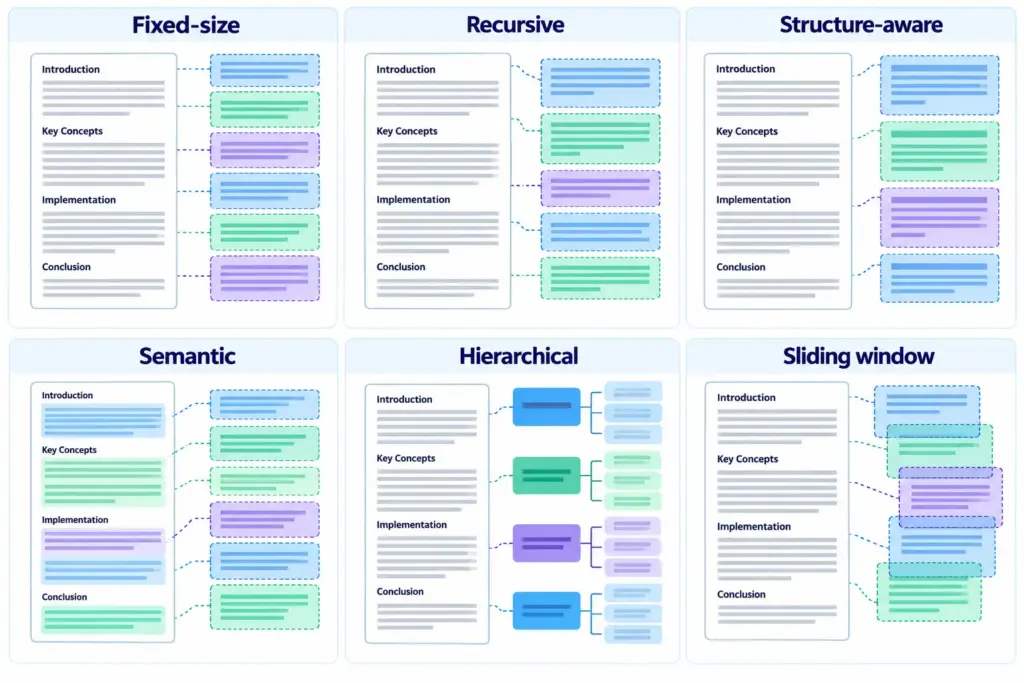
The following strategies are building blocks. A production pipeline may route different document types to different splitters rather than force one method across the entire corpus.
1. Fixed-size chunking
Fixed-size chunking splits text by a configured number of characters, words, or tokens. It is simple, fast, reproducible, and useful as a baseline.
Its weakness is structural blindness. A fixed boundary can cut through a sentence, clause, list, or table. Token-based boundaries are usually more relevant to model limits than character counts, but tokens still do not represent meaning.
Use fixed-size chunking when source structure is weak, content is relatively uniform, and you need a measurable baseline. Avoid treating the initial setting as the final answer.
2. Recursive chunking
Recursive splitting tries larger natural separators first—sections, paragraphs, lines, sentences, and finally smaller units—until content fits the size constraint. This is a practical default for mixed prose because it preserves some structure without requiring a full semantic pipeline.
The quality depends on separator order and source cleanup. A recursive splitter cannot preserve headings that were lost during PDF extraction. It also needs language- and format-aware separators rather than one universal configuration.
3. Structure-aware chunking
Structure-aware chunking follows explicit document elements such as headings, sections, clauses, list groups, table blocks, slide titles, or XML/HTML nodes. It is often the strongest starting point for well-formed policies, manuals, documentation, knowledge bases, and web content.
The important step is to carry structural context into each unit. A subsection may need its parent headings attached as metadata or a short context prefix. A table needs its title and headers. A clause needs its agreement, section, and effective date. Microsoft’s document-layout chunking guidance provides one implementation example of using document structure during chunking and vectorization.
4. Semantic chunking for RAG
Semantic chunking detects topic changes or groups adjacent sentences by meaning. It can preserve coherent ideas when paragraph boundaries are inconsistent or when a long narrative section contains several themes.
It also introduces cost, parameters, and model dependency. Semantic similarity thresholds that work for one corpus may over-split another. Recent research continues to investigate adaptive chunking methods, but results are not universally superior across datasets. Semantic chunking should therefore compete against a simpler baseline using the same evaluation set.
5. Parent-child or hierarchical chunking
Hierarchical chunking indexes smaller child units for precise retrieval while retaining a link to a larger parent section. The system can retrieve the focused child and then expand to the parent for generation.
This helps when questions target a sentence or clause but the answer needs surrounding context. It also reduces the pressure to choose one chunk size for both search and generation. The trade-off is more complex indexing, deduplication, context assembly, and citation logic.
6. Sliding-window chunking
A sliding window creates overlapping units across a sequence. It is useful when relevant evidence may cross arbitrary boundaries, particularly in transcripts, logs, or text with weak structure.
The cost is duplication. Similar overlapping chunks can occupy several positions in the retrieval results, waste context space, inflate storage, and make citations repetitive. Use deduplication or diversity-aware selection when overlap creates near-identical candidates.
7. Modality- or object-aware chunking
Some content should be split by its native object rather than by prose length:
- Code by declarations, classes, syntax-aware regions, or bounded windows.
- Tables by logical row groups with repeated headers and table-level context.
- Conversations by turns or topic episodes, with speaker and timestamp metadata.
- Tickets by problem, environment, investigation, and resolution fields.
- Catalog or ERP data by records and relationships rather than flattened text.
This strategy requires more ingestion work but avoids destroying the structure that makes the content useful.
How to Choose the Best Chunking Strategy for RAG
The best strategy is the simplest one that consistently retrieves complete, permitted, current evidence for the questions your application must answer.
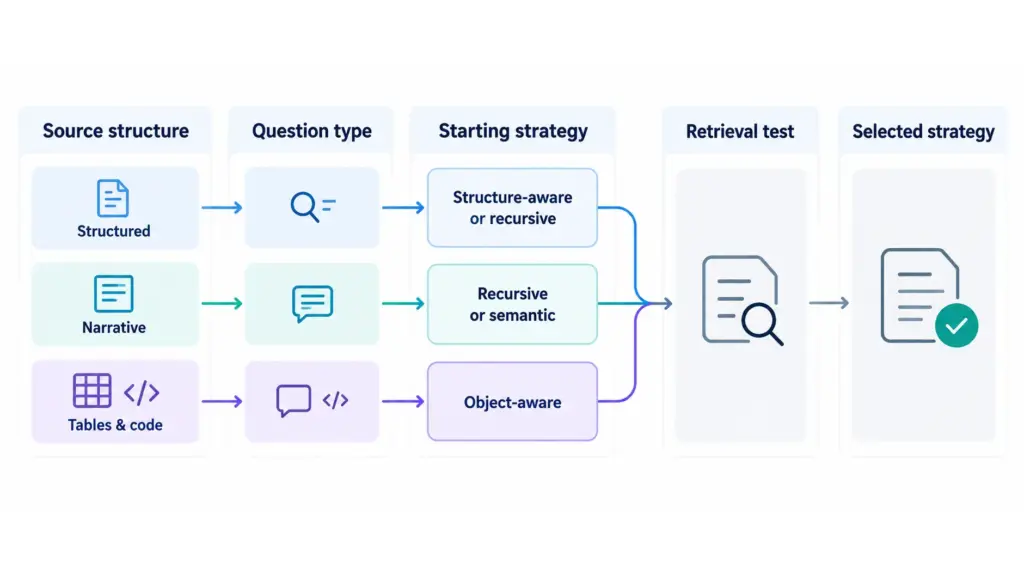
Use this document-type decision matrix
| Source type | Starting strategy | Preserve | Main risk |
|---|---|---|---|
| Clean web pages and product documentation | Structure-aware or recursive | Heading path, lists, links, version | Navigation and boilerplate entering chunks |
| Policies, contracts, and regulations | Clause/section-aware with parent context | Definitions, exceptions, effective date | Retrieving a rule without its qualifier |
| Long reports and research papers | Section-aware, then semantic or recursive subdivision | Section title, page, citation, figure/table reference | Separating evidence from methodology |
| FAQs and support knowledge bases | Question-answer or issue-resolution unit | Product, version, status, audience | Duplicate or obsolete answers |
| Scanned PDFs | Layout-aware extraction before chunking | Page, heading, table structure, OCR confidence | OCR errors becoming indexed evidence |
| Tables and spreadsheets | Schema- and row-group-aware | Headers, units, period, entity, source | Values retrieved without labels |
| Meeting transcripts | Speaker/turn plus topic windows | Speaker, timestamp, meeting, decision status | Attributing a statement to the wrong person |
| Source code | Syntax-aware or sliding window tested by task | File, symbol, language, dependency context | Cutting references from definitions |
| Tickets and incident records | Field-aware object chunks | System, date, severity, resolution, permissions | Mixing symptoms with unrelated fixes |
Start from the evidence unit
Ask: what must stay together for an answer to be correct? The unit might be a definition and its exclusions, a procedure and its prerequisites, a table row and its headers, or a function and the types it uses. Define that unit before selecting token limits.
Match the strategy to actual questions
Create a query set from real or representative user tasks. Include:
- Direct fact questions.
- Questions that use different wording from the source.
- Exact identifier or error-code searches.
- Questions requiring a condition or exception.
- Multi-part questions requiring evidence from more than one section.
- Questions that should return no answer.
- Permission-sensitive questions.
If you tune only against broad topic questions, the pipeline may fail on the precise questions that matter in production.
Use routing when the corpus is mixed
A company knowledge base may contain HTML documentation, PDFs, tickets, tables, code, and transcripts. One splitter is unlikely to respect all of them. Route each format through an appropriate parser and chunker, normalize common metadata, and evaluate both per-source and end-to-end performance.
How to Choose Chunk Size and Overlap
There is no universally correct RAG chunk size. Chunk size is a constraint to test, not a fact to memorize.
Choosing chunk size
Use these questions to define a starting range:
- How long is a complete evidence unit in this source?
- Does the embedding model represent text of this length effectively?
- How many retrieved units can the generation step use without crowding the context window?
- Do users ask narrow lookup questions or broad synthesis questions?
- Will a reranker evaluate candidate chunks?
- Can the system retrieve a child unit and expand to its parent?
Instead of declaring one number “best,” compare at least a small, medium, and large configuration. Keep the embedding model, retriever, candidate count, reranker, and evaluation questions stable while testing chunk size. Otherwise, you cannot attribute the difference to chunking.
Choosing chunk overlap
Overlap can preserve continuity where boundaries are arbitrary. It is useful when a sentence depends on preceding text, a process crosses a window boundary, or source structure cannot be reliably detected.
Overlap is less useful when natural units are already complete. Repeating the same heading and paragraph across several chunks may produce redundant retrieval, higher indexing cost, and repeated prompt evidence.
Use overlap only after identifying a boundary failure it solves. Then test the smallest overlap that repairs that failure. For structured content, attaching the parent heading or a contextual prefix is often cleaner than copying a large percentage of neighboring text.
Do not confuse model context with chunk size
A model’s large context window does not mean every retrieval chunk should be large. Retrieval still needs to rank useful evidence, control permissions, avoid stale versions, and make citations understandable. Long context can help with generation, while smaller or hierarchical units can still improve discovery.
Metadata That Makes RAG Chunks Safer and More Useful
Chunk text alone is rarely enough for a production system. Metadata enables filtering, freshness, access control, traceability, citations, and better context assembly.
Useful fields may include:
- Stable document and chunk IDs.
- Source URL, repository path, object ID, or storage location.
- Document title and hierarchical heading path.
- Content type and language.
- Product, department, customer, jurisdiction, or business domain.
- Version, effective date, last modified time, and ingestion time.
- Page, section, clause, table, slide, speaker, timestamp, or code symbol.
- Authoritative-source status and lifecycle status such as draft, approved, superseded, or archived.
- Access-control attributes needed to enforce retrieval permissions.
- Parent ID and neighboring-unit references for context expansion.
- Extraction method and quality indicators when OCR or parsing may be unreliable.
Do not expose sensitive metadata to the language model merely because the retrieval system uses it. Separate fields needed for filtering and authorization from fields safe to include in generated context.
Metadata is not a substitute for source governance. If two conflicting policy versions are indexed as equally current, precise chunks can still produce the wrong answer. Establish an authoritative source, version rules, deletion behavior, and reindexing triggers.
A Practical RAG Chunking Evaluation Workflow
Chunking should be evaluated at retrieval level before teams judge only the final prose answer.
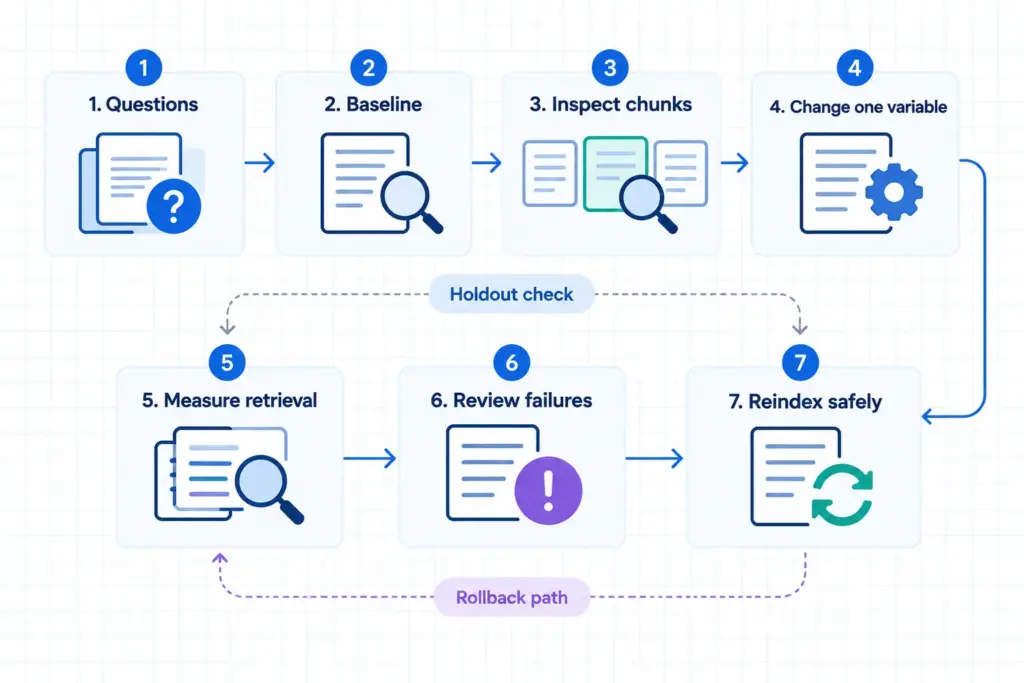
Step 1: Build a representative evaluation set
For each question, identify the source evidence that should be retrieved. Include normal, difficult, ambiguous, negative, and permission-sensitive cases. Keep a separate development set for tuning and a holdout set for confirming results.
Step 2: Establish a simple baseline
Use a straightforward fixed-size or recursive configuration. Record the parser, splitter, size, overlap, embedding model, metadata filters, retriever, top-k settings, and reranker configuration.
Step 3: Inspect chunks before running retrieval
Sample units across every document type. Check whether:
- Headings travel with the related text.
- Tables retain titles, headers, and units.
- Lists and procedures remain coherent.
- Definitions remain connected to exceptions.
- Duplicate boilerplate has been removed.
- Restricted content carries the correct permission metadata.
- OCR or parser artifacts are visible and flagged.
Step 4: Compare one meaningful change at a time
Test a different size, overlap, structural splitter, semantic boundary method, or parent-child configuration without simultaneously changing the embedding model and retriever.
Step 5: Measure retrieval evidence
Evaluate whether the expected evidence appears in the candidate set, how highly it ranks, whether irrelevant chunks dominate, and whether returned units contain enough context to support the answer. Track results by question type and document type, not only as one average.
For a broader treatment of retrieval and answer metrics, use WebbyCrown’s guide to RAG evaluation metrics. This article owns chunking experiments; the evaluation guide owns the full measurement framework.
Step 6: Review failure patterns
Classify failures rather than merely adjusting numbers:
- Evidence was never extracted.
- Evidence was split across boundaries.
- A chunk mixed too many topics.
- Metadata filters excluded the correct unit.
- An obsolete duplicate outranked the current source.
- Exact terminology was missed by semantic retrieval.
- Too many overlapping chunks crowded out diverse evidence.
- The question required multi-hop or multi-document retrieval.
Step 7: Reindex deliberately
Changing chunking usually changes chunk IDs, embeddings, index size, citations, and cache behavior. Version the ingestion configuration, test migration, preserve rollback capability, and reconcile deletions so old chunks do not remain searchable.
Common RAG Chunking Mistakes
Copying a framework default into production
LangChain and other frameworks make splitting convenient, but a default is an implementation starting point—not proof that the setting fits your data. IBM’s tutorial on chunking strategies with LangChain and watsonx.ai illustrates configurable approaches; your team must still record the exact splitter and parameters and validate them against your corpus.
Using one strategy for every source
A single recursive splitter across web pages, tables, scanned PDFs, support tickets, and source code creates inconsistent evidence. Route by format and normalize metadata afterward.
Increasing overlap to hide bad parsing
Overlap cannot reconstruct a missing heading, broken table, or incorrect OCR extraction. Fix parsing and document structure first.
Evaluating only the final answer
A fluent answer can hide weak evidence. Inspect which chunks were retrieved, which were used, and whether they support each material statement.
Ignoring duplicates and versions
Repeated templates, navigation, exported copies, and obsolete documents can dominate retrieval. Deduplicate content and make lifecycle metadata enforceable.
Splitting first and adding permissions later
Access control must remain attached to every derived chunk. A retrieval layer that ignores source permissions can disclose restricted content before the model generates an answer.
Assuming semantic chunking is always superior
Semantic methods can help when meaning does not align with formatting, but they add complexity and may not outperform simpler approaches on every corpus. A 2026 study of chunking strategies on structured academic texts found that a tested cluster-based semantic method did not outperform simpler alternatives under its configuration. Treat the method as a hypothesis, not a label of quality.
When Not to Add a More Advanced Chunker
Do not add semantic, agentic, or adaptive chunking merely because it sounds more sophisticated. A simple structure-aware or recursive splitter may be preferable when:
- Documents are clean and consistently structured.
- Questions target self-contained sections.
- The baseline retrieves the expected evidence reliably.
- Latency, ingestion cost, reproducibility, or auditability is more important than marginal flexibility.
- The actual failure lies in parsing, source quality, stale versions, permissions, retrieval, or reranking.
Advanced chunking is justified when measured failures show that simpler boundaries repeatedly lose coherence or when different document types require different treatment. The operational cost includes more complex ingestion, more parameters, harder debugging, and possible reindexing when models or rules change.
RAG Chunking Checklist
- The source parser preserves the structures that matter.
- Every document type has an intentional routing rule.
- Each chunk contains a complete or recoverable evidence unit.
- Parent headings and necessary qualifiers remain available.
- Tables retain labels, headers, units, and source identity.
- Chunk size was tested rather than copied.
- Overlap solves a demonstrated boundary problem.
- Metadata supports filtering, versions, citations, and permissions.
- Boilerplate, duplicates, and superseded versions are controlled.
- The evaluation set represents real questions and difficult cases.
- Retrieval evidence is inspected separately from answer fluency.
- Ingestion configurations and indexes are versioned and reversible.
Frequently Asked Questions
What is the best chunking strategy for RAG?
There is no universal best strategy. Start with source structure and real query patterns. Structure-aware or recursive chunking is a practical baseline for many text collections, while parent-child, semantic, or object-aware methods are useful when measured failures justify the extra complexity.
What chunk size should I use for RAG?
Choose a starting range based on the length of a complete evidence unit, the embedding model, and the questions users ask. Compare multiple sizes with the same retrieval configuration and measure whether expected evidence is found and remains complete.Chunking is the ingestion step that turns a document, page, record, or codebase into smaller retrieval units. Each unit may be embedded, indexed, filtered, ranked, and eventually supplied to a language model as evidence. Microsoft’s RAG chunking-phase guidance likewise treats chunking as a preparation and indexing decision rather than a universal token setting.The quality depends on separator order and source cleanup. A recursive splitter cannot preserve headings that were lost during PDF extraction. It also needs language- and format-aware separators rather than one universal configuration.
How much overlap should RAG chunks have?
Use the smallest overlap that fixes a demonstrated boundary problem. Natural document boundaries may need little or no copied overlap, while weakly structured transcripts or sliding windows may need more. Excessive overlap creates duplicate candidates and wastes context.
Is semantic chunking better than fixed-size chunking?
Not automatically. Semantic chunking may preserve topics better in irregular narrative text, but it costs more and depends on thresholds or models. Test it against a fixed or recursive baseline on the same documents and questions.
What is hierarchical chunking in RAG?
Hierarchical or parent-child chunking indexes small child units for precise retrieval and links them to larger parent sections for context. It is useful when search needs narrow evidence but generation needs the surrounding explanation.
Does LangChain choose the best chunking strategy automatically?
LangChain provides text splitters and integration utilities, but the team still chooses the splitter, separators, size, overlap, and evaluation method. Framework convenience does not remove the need to test the configuration against the application’s corpus.
How should tables be chunked for RAG?
Preserve the table title, column headers, units, relevant row group, source, and period together. Avoid flattening values into text that loses their labels. Large tables may require schema-aware row groups plus metadata filters or a structured-query path.
How should source code be chunked for RAG?
Test syntax-aware regions, declarations, and bounded sliding windows against the code task. Preserve file paths, symbols, language, and necessary cross-file context. A 2026 study on chunking for retrieval-augmented code completion further supports evaluating code chunking against the specific task rather than assuming that splitting only by function is always optimal.
Does changing chunking require reindexing?
Usually yes. New boundaries change chunk text, IDs, embeddings, index size, and citations. Version the ingestion pipeline, build the new index safely, compare it with the current version, and retain a rollback path.
How do I know whether chunking is causing poor RAG answers?
Inspect the retrieved evidence. If the correct source was parsed but the relevant text is missing, split across chunks, stripped of qualifiers, or crowded out by duplicates, chunking is likely involved. If the correct complete chunk is retrieved but ignored, investigate ranking, context assembly, prompting, or generation instead.
Conclusion
RAG chunking is not a one-time token-setting decision. It is the design of the evidence units your retrieval system can find, filter, rank, cite, and authorize. Start with natural source structure, preserve the context required for correctness, add overlap only for a known boundary problem, and use metadata to control identity, versions, permissions, and traceability.
Most importantly, evaluate with representative questions. A simple splitter that retrieves complete evidence consistently is more valuable than an advanced method selected by name alone. When mixed formats or repeated failures demand more, introduce routing, hierarchy, semantic boundaries, or object-aware methods one measured change at a time.
If your team needs to design or rebuild an ingestion and retrieval pipeline around real enterprise documents, WebbyCrown’s RAG development services can support source analysis, architecture, evaluation, security, and production implementation.