Summarize This Article With AI
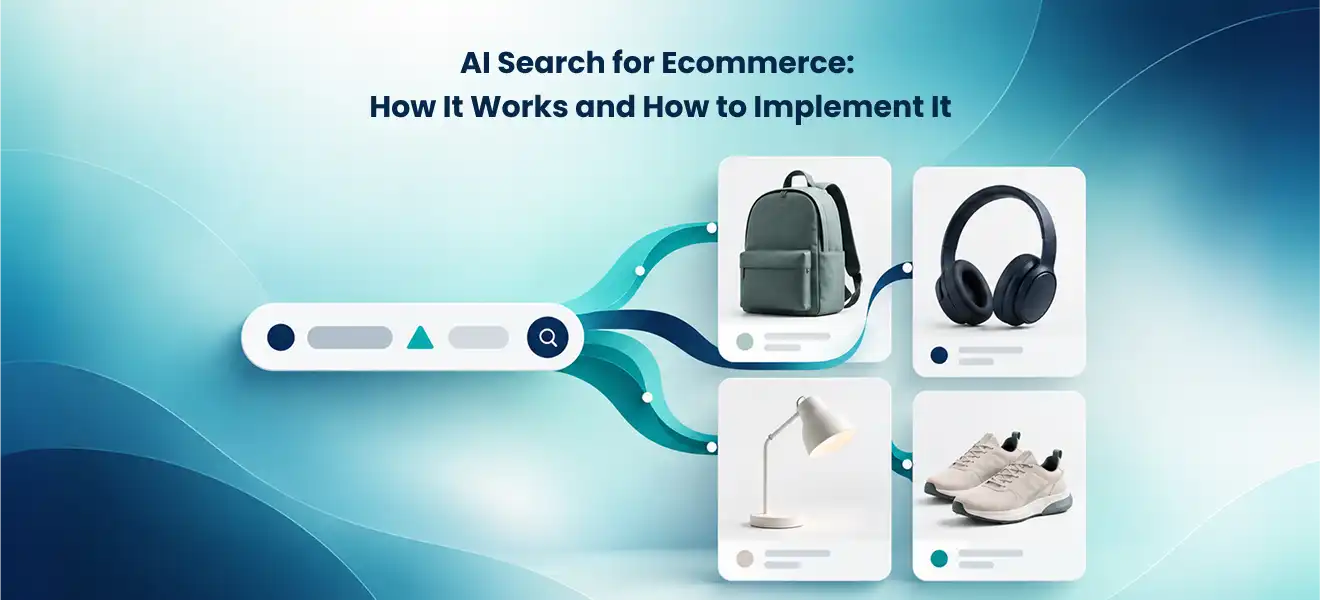
AI search for ecommerce helps shoppers find products by interpreting what they mean, not only matching the exact words they type. A practical implementation combines keyword search for precise names and SKUs, semantic matching for natural-language needs, and strict catalog filters for price, availability, region, and product eligibility. The objective is useful, accurate product discovery—not an AI chatbot that invents product details. Start with clean catalog data, test against real shopping queries, and measure whether customers find purchasable products faster.
Key takeaways
- Hybrid search is often a sensible starting point: keep exact-match retrieval for product codes and combine it with meaning-based retrieval for descriptive queries.
- A relevant-looking item is not necessarily purchasable. Availability, price, customer eligibility, and fulfillment rules must remain authoritative.
- Better search starts with product attributes, variant mapping, synonym coverage, and dependable catalog updates—not a new AI model alone.
- Measure result quality and business outcomes separately, using query-specific tests before any wider rollout.
- Add generative answers or personalization only after retrieval, data controls, and operational monitoring are reliable.
A shopper might enter “compact backpack for a rainy commute under $120.” The product catalog may say “weather-resistant 18-liter daypack,” with no mention of commuting. Keyword-only matching can miss the connection; an unconstrained semantic model can find relevant-looking packs that cost $180 or cannot ship to the shopper. The useful solution combines both forms of matching while enforcing the store’s actual selling rules.
1. What Is AI Search for Ecommerce—and When Is It Useful?
AI-powered ecommerce search is a product-discovery system that can use language understanding, machine learning, vector representations, or learned ranking signals to interpret shopper intent and retrieve suitable products. It operates inside the store or commerce experience. It is not the same thing as appearing in Google Search, being cited by an AI answer engine, or giving a shopping agent permission to place an order.
Keyword, semantic, hybrid, and conversational search
| Approach | What it does well | Where it struggles | Useful ecommerce query |
|---|---|---|---|
| Keyword / lexical | Exact titles, brands, part numbers, model codes, structured terms | Descriptions that use different vocabulary | “AB-420 replacement cartridge” |
| Semantic / vector | Intent, synonyms, paraphrases, broader needs | Exact model numbers; hard price and stock rules without filters | “quiet desk fan for a small bedroom” |
| Hybrid | Combines lexical precision and semantic discovery | Requires tuning, catalog hygiene, and evaluation | “AB-420 cartridge for low-odor printing” |
| Conversational layer | Clarifies preferences and explains shortlist trade-offs | Can invent unsupported claims if not grounded in eligible products | “Which one fits a carry-on and a 15-inch laptop?” |
| Refunded | Create return only if goods come back | Restock after inspection | |
| Failed | Cancel or delete quotation | Releases any hold |
The distinction matters because not every store needs the same capabilities. An industrial parts catalog with long part numbers may get more value from robust keyword matching, filters, and synonym dictionaries than from a conversational assistant. A lifestyle catalog with descriptive queries may benefit from semantic retrieval. A mixed B2B/B2C catalog usually needs both, followed by eligibility checks.
Microsoft’s hybrid-search documentation explains why vector search can surface conceptually similar content while full-text search remains valuable for exact identifiers. The underlying trade-off also applies to product retrieval, although ecommerce adds transactional constraints that an ordinary document-search example does not have.
AI search is not the same as recommendations. Search responds to an expressed query; recommendations may suggest products based on context or behavior even when no query exists. It is also not the same as an autonomous purchasing agent. WebbyCrown’s guide to agentic commerce covers the broader journey in which an agent may compare options and, with permission, take shopping actions. This article focuses on the narrower, foundational task of finding accurate products inside an owned storefront.
A quick fit test
Prioritize a search improvement project when query logs show descriptive searches with weak results, frequent zero-result pages despite relevant inventory, users repeatedly rewriting searches, or complex variants that are hard to discover. Deprioritize a large AI rebuild when the main problem is missing product titles, broken filters, slow pages, or an out-of-date inventory feed. Fix those fundamentals first.
2. How an AI-Powered Product Search System Works
A reliable system begins with a source of truth for products and ends with a storefront rendering items the customer can actually buy. The retrieval model is only one component.
Step 1: Prepare the catalog and define trusted fields
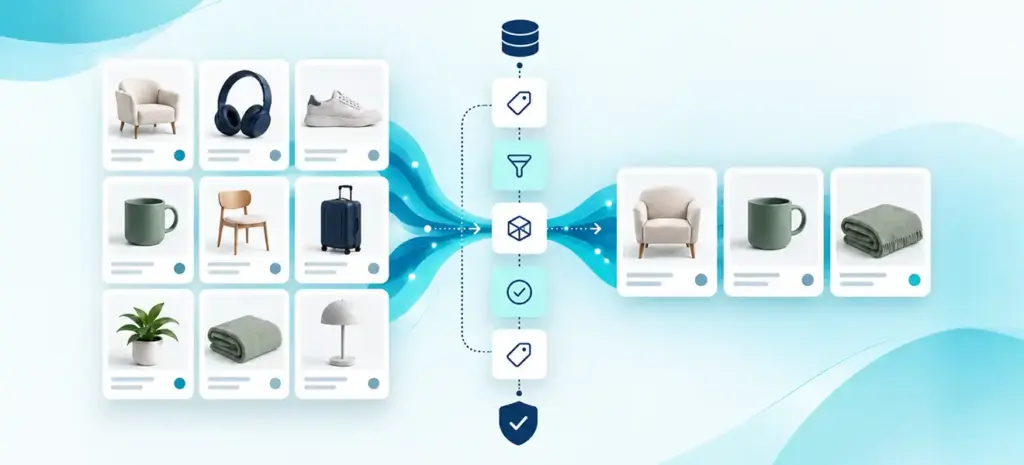
Start with stable `product_id`, `variant_id`, and `sku` values, plus clear product names, descriptions, categories, materials, dimensions, compatibility, searchable attributes, images, and product URLs. Keep fields such as price, currency, market, availability, and B2B eligibility mapped to authoritative commerce systems. If those fields change quickly, the search index must not be treated as a permanent guarantee.
This is not simply “put every description into an embedding.” Product meaning also lives in structured fields: “waterproof” and “water-resistant” are not interchangeable promises, dimensions are numerical constraints, and a particular printer cartridge cannot be replaced by a semantically similar but incompatible one. Preserve exact structured values alongside searchable text.
Step 2: Build searchable representations
A keyword index supports exact terms, product codes, and phrase matching. A semantic index represents descriptions and queries in a way that can find conceptual similarities. A hybrid system retrieves candidate products from both, deduplicates and merges candidates, and may rerank a limited shortlist. Avoid pushing the entire catalog through a language model for every query.
OpenSearch’s hybrid-search documentation describes techniques for combining multiple retrieval methods. Implementation details depend on the selected stack; hybrid retrieval should not be confused with a guarantee of better outcomes for every query.
Step 3: Apply non-negotiable selling rules
Hard filters outrank semantic similarity. The product must be permitted for the user’s market, customer group, and current availability. A $120 budget cannot be overridden because a $180 backpack is semantically more attractive. A B2B-only price must not leak to an unauthenticated retail visitor. For especially volatile stock and prices, verify the final item values against the commerce system at the point where a shopper acts.
A useful query-time sequence is: understand the search request; retrieve lexical and semantic candidates; enforce structured constraints and permissions; merge and rank eligible products; show explainable filters and product links; recheck price and availability where required. If an AI component becomes unavailable, degrade gracefully to conventional catalog search rather than showing invented stock.
Step 4: Return useful storefront controls
The UI needs more than a clever top result. Keep sort controls, visible price ranges, attributes, accessibility labels, useful empty states, variant handling, and predictable pagination. Shoppers must be able to refine results themselves. A conversational answer should cite or link the exact products it references; it should not replace the product detail page, cart validation, or checkout rules.
On Shopify, for example, the official Storefront search query and predictiveSearch query provide different built-in retrieval surfaces. Predictive search supports suggestions as a user types; its documentation describes specific arguments and limits. Neither endpoint should be described as a turnkey guarantee of custom semantic search. A custom layer needs a separate engineering decision and compatibility review.
3. Implementation Checklist: From Search Logs to Production
A staged rollout is usually safer than replacing all storefront search in one release. The sequence below helps ecommerce owners compare what can be configured, integrated, or engineered before committing to AI complexity.
Phase 1: Establish the baseline
Export a representative set of search queries and map them to clicks, zero-result rates, refinements, product views, add-to-cart actions, and purchases where tracking is reliable. Segment the set: exact SKU searches, category queries, problem-oriented language, ambiguous requests, misspellings, multilingual requests, and zero-result queries. Remove personal data and honor the store’s retention rules.
Ask a merchandiser and a product specialist to label what a satisfactory result looks like for each query. A phrase such as “replacement filter for model X” needs compatibility first, while “gift for a weekend hiker” permits broader exploration. Document the difference before evaluating models.
Phase 2: Fix catalog quality and scope
Assign ownership for product attributes, synonyms, variant grouping, inventory events, market restrictions, and catalog refreshes. Define the pilot’s categories and markets. Do not launch a search service across a massive catalog when only one collection has dependable descriptions and filters.
| Readiness check | A pass looks like | If it fails |
|---|---|---|
| Identity | Every sellable variant maps to a stable SKU/ID | Repair duplicate or missing IDs |
| Attribute quality | Key dimensions, materials, and compatibility are structured | Improve the source catalog first |
| Availability | Search can suppress or clearly label unavailable items | Connect inventory status or restrict pilot |
| Price / market | Currency, market and customer pricing rules are enforced | Keep source-of-truth checks outside the model |
| Freshness | New products, edits and deletions reach the index predictably | Add event updates and reconciliation |
| Analytics | Search, clicks and downstream actions can be connected responsibly | Fix instrumentation before claiming improvement |
Phase 3: Start with the simplest sufficient retrieval model
Compare the current baseline with improved keyword search first. Add controlled synonyms and typo handling where they solve observed issues. Then test hybrid search on queries where relevance still fails. Reranking and generative explanations are optional stages, not prerequisites. For small catalogs, a well-structured filter and rules system may remain the better long-term choice.
Phase 4: Run offline evaluation before exposure
Create a labeled query set covering everyday, rare, and high-risk terms. Score whether the most useful eligible products appear near the top and whether critical exact matches remain present. Track failures by query class, not only an overall score. A strong average can hide unacceptable results for medical fit, safety specifications, replacement parts, or protected B2B prices.
Phase 5: Release gradually with a rollback path
Use a staff-only preview or a limited traffic experiment. Keep the previous search route available. Define who can stop the rollout, how to investigate bad results, and how merchants override misleading synonyms or ranking behavior. Monitor p95 latency, API failures, stale indexes, empty results, and affected inventory categories. Search should not block cart or checkout if the optional AI service is down.
This stage-gated approach mirrors broader production engineering disciplines rather than assuming a successful prototype is production-ready. WebbyCrown’s AI product engineering lifecycle guide provides additional context for defining an AI feature’s acceptance criteria and operating responsibilities.
4. How to Measure Search Quality and Business Impact
Search quality and sales outcomes need separate measurement. More purchases during an experiment do not prove search was the cause without a credible comparison design; likewise, a higher relevance score does not guarantee a better customer experience.
| Metric | What it answers | Interpretation caution |
|---|---|---|
| Zero-results rate | How often does a query return no eligible products? | A valid empty result may be better than a misleading match |
| Search-to-product click rate | Do shoppers find a result worth opening? | High clicks may still lead to wrong products |
| Query reformulation rate | Do shoppers need repeated searches? | Clarification can be normal for broad exploration |
| Relevance at top results (e.g., nDCG@10) | Do labeled suitable products appear near the top? | Requires consistent human judgments and query mix |
| Search-assisted add-to-cart / conversion | Do search sessions reach later purchase steps? | Compare cohorts carefully; avoid misleading attribution |
| p95 search latency | Is search predictably fast for most requests? | Median alone can hide poor tail performance |
| Invalid-result incidents | Did search show wrong stock, incompatible products, or unauthorized prices? | Some incidents warrant immediate rollback |
For a controlled A/B test, decide the primary success metric before launch, split exposure consistently, keep pricing and promotions comparable, and review mobile versus desktop and new versus repeat shoppers. An improvement in zero-results rate accompanied by a rise in wrong-item clicks is not a win.
Illustrative evaluation example—not a real WebbyCrown or client result: A retailer labels 200 historical queries, including 40 model-number searches. A candidate hybrid configuration improves broad descriptive-query judgments but misses three critical model-code results that the baseline returns correctly. The correct next step is to adjust exact-match priority or query routing and retest, not to declare that hybrid search is better on aggregate.
A useful operational dashboard combines relevance, transactional correctness, and service health. It should show which query families are failing and give a responsible person a way to investigate them. Publish experiments only when there is real evidence and appropriate permission; do not advertise an invented uplift percentage.
5. Costs, Risks, and When Not to Add Generative AI
The cost of ecommerce AI search comes from several workstreams: catalog cleanup; integration with commerce, inventory, and pricing systems; search infrastructure and index updates; optional embeddings and model inference; evaluation; storefront UX; analytics; security review; and ongoing maintenance. It is misleading to quote a model’s per-token fee as the total implementation price.
A realistic budget uses the formula one-time setup + integration and catalog work + testing and rollout + recurring infrastructure and support. Its amount depends on catalog size, update frequency, markets and languages, required latency, traffic, variants, and the complexity of the store’s rules. No general-purpose price range fits every implementation, and no figure here is a WebbyCrown quote.
Common failure modes and their controls
- Stale results: A newly sold-out product stays searchable. Use event-driven updates, scheduled reconciliation, and availability rechecks at interaction time.
- Semantic overreach: The engine suggests a similar-looking but incompatible part. Prioritize exact identifiers, structured compatibility filters, and negative test cases.
- Invented attributes: A generated explanation claims “waterproof” when the catalog says “water-resistant.” Generate only from approved product fields, require product references, or skip generated descriptions.
- Unauthorized visibility: Search exposes restricted wholesale prices or products. Apply authentication, customer-group and regional permissions before retrieval or display, not in the model prompt alone.
- Unbounded operating cost: Expensive reranking or generation runs on every keystroke. Debounce requests, cache safely where appropriate, limit candidates, and budget for peak periods.
- Bias toward margin over fit: Merchandising boosts bury products that satisfy the request. Keep business boosts transparent, bounded and subordinate to eligibility and core relevance.
- Privacy drift: Search logs are stored longer than necessary or used for personalization without an appropriate basis. Minimize and govern logs, consent signals, and access privileges.
When simpler search is the better decision
Stay with conventional search when the catalog is small and exact, shopper queries are mostly SKU codes, filters already solve discovery problems, or the current product data is unreliable. Also defer generative explanations if you cannot trace every claimed price and feature to authoritative product records. An AI-powered storefront is not automatically more accurate, faster, or profitable.
For complex implementations, the engineering question is how to connect and operate retrieval safely inside existing commerce infrastructure. WebbyCrown’s ecommerce development services describe its broader storefront and integration work; the article’s decision framework should help you assess whether a configuration change, targeted search integration, or custom build is justified before commissioning one.
6. A Practical Decision Framework for Ecommerce Teams
Start by documenting five things: (1) your main failed query types, (2) a catalog quality scorecard, (3) the selling constraints that cannot be broken, (4) a representative relevance test set, and (5) the outcomes that would justify rollout. Use these to choose the least complex approach that solves a demonstrable problem.
| Situation | Recommended first move | Do not assume |
|---|---|---|
| Exact SKU and part-number queries dominate | Improve lexical ranking, filters and typo handling | Semantic-only search is inherently better |
| Shoppers describe use cases rather than product names | Trial hybrid retrieval on a labeled query set | Vectors can enforce price/stock constraints by themselves |
| Multiple markets or wholesale customer groups | Fix permissions, catalog mapping and market filtering | One global index can safely expose every offer |
| High product change rate | Engineer updates, freshness monitoring and rechecks | Embeddings alone keep prices and availability current |
| Search is accurate but users need advice | Test optional explanations grounded in product records | A generative assistant should control checkout |
Owner checklist before approval: Name an ecommerce product owner, merchandising reviewer, data/integration owner, and search-operations owner. Define explicit acceptance and rollback criteria. Keep an accessible feedback channel for storefront staff, because the person who sees “wrong size” complaints may detect problems before a technical monitoring alert.
The most durable ecommerce AI search projects do not begin with “which model should we buy?” They begin with: which shopping questions are currently unanswered, and which data and controls will make the answer dependable? A modest, auditable hybrid search pilot may resolve them. If not, the same evidence clarifies whether a more capable AI product is worth building.
Frequently Asked Questions
Is AI search for ecommerce the same as Google SEO?
No. Ecommerce AI search helps visitors discover items inside a store. Google SEO helps pages become discoverable in external search results. Both benefit from clear product data, but they have different systems, ranking signals, and measures of success.
Does AI-powered product search require a large language model?
No. Semantic embeddings, lexical ranking, filters, and learned ranking models can work without generated text. A large language model is optional for query interpretation or explanatory responses and brings extra cost and quality controls.
What is the advantage of hybrid search over semantic-only search?
Hybrid retrieval can preserve exact codes and brand or model matches while recognizing paraphrases. It still needs tuned ranking, structured filters, and evaluations; it is not guaranteed to outperform every keyword-only baseline.
Can AI search respect live inventory and regional pricing?
Yes, if those constraints are wired to authoritative commerce data and enforced as rules. A vector similarity score cannot decide whether a product is in stock or legally sellable in a market. Revalidate fast-changing values when necessary.
Will an AI search feature work with Shopify or WooCommerce?
Potentially. Both ecosystems offer native search capabilities and integration paths, but custom AI behavior, sync patterns, permissions, and theme compatibility require a scoped technical assessment. Do not assume any specific app or connector provides features it does not document.
How much product data is needed before starting?
There is no universal minimum catalog size. A pilot needs enough representative, accurately labeled products and real query examples to evaluate whether retrieval improves over the current search. Quality and coverage matter more than an arbitrary item count.
How should a store handle zero-result searches?
First check whether the catalog truly lacks an eligible item. Then offer corrections, related categories, or a clearly labeled alternative without inventing products. Track whether a zero-result page came from indexing failure, poor synonyms, or legitimate absence.
Can AI search improve ecommerce conversion rates?
It may help some shoppers find suitable products, but there is no guaranteed uplift. Evaluate conversion alongside relevance, product correctness, and experiment design so that promotions, seasonality, or shopper differences are not mistaken for a search effect.
What should be tested before launching semantic search?
Test exact SKUs, size/fit constraints, incompatible parts, price caps, out-of-stock items, multi-market eligibility, language variants, stale feed events, API failures, mobile UI, and rollback behavior. Include ordinary and high-risk queries.
When should a business choose custom AI search instead of existing store search?
Consider a custom layer when documented failures persist after baseline optimization and cannot be solved with available configuration or suitable integration. Require a scoped architecture, data plan, operating costs, monitoring responsibility, and measurable acceptance criteria.
Conclusion
AI search for ecommerce is most useful when it solves a real product-discovery problem without weakening the rules that make a store trustworthy. Keep exact matching where precision matters, use semantic retrieval where language is flexible, enforce price and availability as hard constraints, and test with real shopper queries. If you are planning a controlled pilot or need to assess a custom integration, WebbyCrown’s AI product engineering services provide a relevant next step for discussing architecture and production readiness.